AI Development
AI Observability for Production Applications: Monitoring LLMs, Agents & RAG Pipelines
October 3, 2026
October 3, 2026
Key Takeaways:
Traditional monitoring misses what matters most: AI systems can appear perfectly healthy on infrastructure dashboards while quietly producing wrong or harmful outputs.
Agents fail in fundamentally different ways: multi-step reasoning introduces failure modes, like inter-agent misalignment, that single-call monitoring can't catch.
RAG pipelines need retrieval and grounding checked separately: a confident, well-written answer can still be entirely unsupported by the retrieved source material.
The market is growing because the gap is real: rapid LLM observability market growth reflects genuine, unmet enterprise need, not hype.
Strategy matters more than tools alone: clear quality definitions, full-layer instrumentation, and continuous production evaluation separate effective observability from checkbox monitoring.
A traditional app crashing is easy to spot: an error log, a 500 status code, a clear failure point. An AI system quietly giving wrong answers, hallucinating facts, or an agent looping endlessly through unnecessary steps?
That often goes unnoticed until a user complains, or worse, until it's already caused real business harm.
This is exactly the gap AI observability closes. As more businesses move LLMs, autonomous agents, and RAG pipelines from prototypes into actual production, traditional monitoring tools simply weren't built to catch the kinds of failures unique to AI systems: subtle quality degradation, retrieval mismatches, runaway reasoning loops.
This guide breaks down what observability actually means for each of these three components, the metrics that matter, the tools available, and how to build a strategy that catches problems before users do.
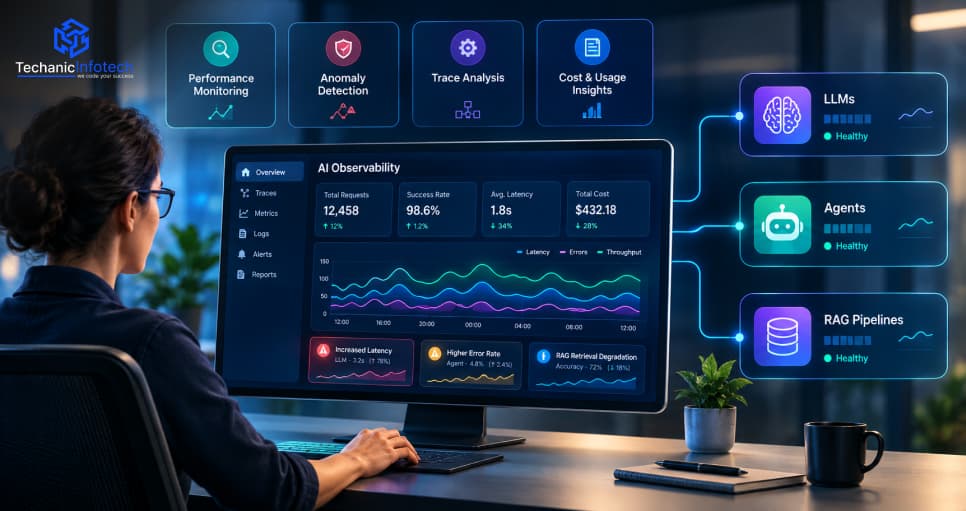
Traditional monitoring answers a simple question: did the system respond? AI observability answers a harder one: was the response actually good? That distinction is exactly where production AI failures quietly originate, hidden behind dashboards showing perfectly healthy uptime.
A traditional app crashing is obvious: an error, a failed request, a clear signal. An LLM can respond in 400 milliseconds with a completely wrong, hallucinated, or unsafe answer while every infrastructure metric shows green. Observability scores behavior and quality, not just whether a request technically succeeded.
This isn't a theoretical concern. The LLM observability platform market is projected to grow from $2.69 billion in 2026 to $9.26 billion by 2030, at a 36.2% CAGR, reflecting how quickly enterprises are realizing standard APM tools simply weren't built for non-deterministic AI outputs.
Production use has outpaced observability maturity. 57% of organizations now run AI agents in production. Yet, observability and evaluation remain the lowest-rated part of the AI stack, with fewer than one in three teams actually satisfied with their current tooling.
Ignoring this gap carries real, measurable risk. Enterprise losses from hallucinations alone are estimated at $67.4 billion in 2024, and Gartner predicts 40% of organizations deploying AI will use dedicated AI observability to monitor model performance by 2028, up sharply from current adoption levels.
Getting an LLM feature working in a demo is easy; keeping it reliable once real users depend on it is where most teams struggle.
Moving from AI pilot to production exposes failure modes that simple testing never surfaces, making the right metrics essential.
Unlike traditional software, a slow, confidently wrong answer is often worse than an obvious error.
Tracking hallucination rate- how often the model generates unsupported or fabricated claims- requires dedicated evaluation rather than relying on standard uptime or error-rate dashboards that miss this entirely.
Response time matters, but so does cost, since every token processed carries a price.
Teams need visibility into both how fast responses arrive and how many tokens each interaction consumes, since unmonitored usage can quietly turn a reasonable feature into an expensive liability.
Model behavior can shift subtly over time, whether from provider-side updates or changing user input patterns, causing responses that once performed well to gradually degrade.
Monitoring for this drift catches quality decline before it becomes visible to users or shows up in complaints.
Traditional logs can't reproduce the non-deterministic nature of LLM failures.
Trace-level replay, capturing the full input, intermediate reasoning, and output of each request, has become a baseline requirement for teams needing to actually debug why a specific response went wrong.
Apps handling sensitive topics or regulated data need monitoring for toxic, biased, or non-compliant outputs in real time.
This matters increasingly as regulations like the EU AI Act push observability from a nice-to-have toward a genuine compliance requirement for production systems.
The same prompt can produce different outputs across runs, making traditional testing and monitoring approaches, built around deterministic, repeatable behavior, fundamentally insufficient.
This unpredictability is the central challenge driving demand for purpose-built LLM observability rather than adapted traditional APM tools.
Monitoring a single LLM call is hard enough, but agents that chain together multiple reasoning steps, tool calls, and decisions introduce an entirely different category of failure.
Tracking this multi-step behavior requires observability built specifically around how agents actually operate.
Agent failures rarely look like simple errors. Multi-agent systems have 14 distinct failure modes across three categories: system design failures, inter-agent misalignment, and task verification problems, meaning teams need observability that distinguishes between these categories rather than treating every failure identically.
Every step of the agentic development lifecycle, from initial retrieval through reasoning and final action, needs to be captured as a traceable span.
This hierarchy lets teams pinpoint exactly where in a multi-step process things went wrong, rather than only seeing the final, often confusing, output.
Agents that loop unnecessarily or retrieve redundant information waste significant compute.
Enterprises using proper tracing report an average 40% reduction in token waste once they can actually see and optimize these inefficient agent loops, directly turning observability into measurable cost savings.
Since agents chain multiple steps together, latency compounds with each additional call, making response time a particularly significant production challenge.
Teams need visibility into which specific step in the chain is slowing down the overall task, not just the total end-to-end time.
Unlike a single LLM response, agent tasks need verification that the entire multi-step objective was actually accomplished correctly, not just that each step technically executed.
This requires evaluation logic that checks the outcome against the original intended goal.
Despite rapid agent deployment, this remains the industry's weakest spot. 73% of enterprises require AI agent monitoring in production, yet 63.4% cite a lack of adequate observability tooling as a major barrier, revealing a genuine, unresolved gap between need and available solutions.
A RAG system can fail in ways that look nothing like a typical bug, confidently citing the wrong document, retrieving irrelevant context, or generating answers that technically sound grounded but aren't.
Monitoring these pipelines requires tracking retrieval and grounding separately from the model itself.
Before evaluating anything the model generates, teams need to confirm the retrieval step actually pulled relevant, useful information in the first place.
Scoring retrieved documents against the original query catches silent retrieval failures that would otherwise propagate errors into every downstream step of the pipeline.
Even with relevant documents retrieved, the generated response still needs verification that it actually reflects what those documents say, rather than drifting into unsupported claims.
Faithfulness checks compare generated output against retrieved source material, catching the specific failure mode unique to RAG systems.
Since retrieval depends on semantic similarity between query and document embeddings, monitoring needs to catch cases where the embedding model fails to surface conceptually relevant results, even when exact keyword matches exist elsewhere in the knowledge base being searched.
Teams need visibility into how much of the retrieved context actually gets used meaningfully by the model, versus context that gets retrieved but ignored or improperly weighted.
Poor utilization signals either retrieval problems or prompt design issues worth investigating further.
Applying top DevOps principles- continuous monitoring, automated alerting, and clear rollback paths- to RAG pipelines specifically helps teams catch degradation in retrieval quality or grounding accuracy before it reaches users, rather than discovering problems only after complaints start arriving.
When a RAG system cites specific sources for its claims, that attribution needs to be genuinely accurate, not just plausible-sounding.
Monitoring source attribution catches cases where the model cites a document that doesn't actually support the specific claim being made.
Knowledge bases change over time, and retrieval systems built on stale indexes quietly return outdated information without any obvious error.
Monitoring index freshness and flagging when underlying data sources have updated without a corresponding reindex prevents this silent degradation.
Testing retrieval and generation separately misses failures that only emerge from their interaction.
Comprehensive RAG monitoring needs end-to-end evaluation tracking the full pipeline, from query to final grounded response, to catch issues that component-level testing alone would miss entirely.
The right tooling shapes how quickly teams catch and diagnose AI-specific failures. Here are ten tools consistently showing up in serious production AI observability stacks, each covering different layers of the monitoring challenge.
Offering end-to-end agent observability with prompt versioning, trace replay, and LLM-as-a-Judge evaluation in one platform, MLflow has become a leading choice for teams needing comprehensive visibility without stitching together multiple separate, disconnected tools.
Built specifically for debugging multi-step agent logic, LangSmith integrates naturally into existing CI CD pipeline setups, letting teams catch agent failures during development rather than discovering them only after deployment.
It's particularly strong for tracing complex, multi-agent customer service workflows.
This platform closes the loop between tracing and action, evaluating production traces with dozens of research-backed metrics, alerting on quality and drift, and auto-curating datasets that feed directly back into the next evaluation cycle rather than sitting in an isolated dashboard.
Known for strong drift detection and model performance monitoring, Arize helps teams catch gradual quality degradation in production LLM applications, giving visibility into how model behavior shifts over time as real-world usage patterns and inputs evolve.
An open-source observability platform popular for its flexibility and strong OpenTelemetry integration, Langfuse supports trace instrumentation, cost tracking, and evaluation workflows, appealing to teams wanting more control over their own observability infrastructure.
Extending its established infrastructure monitoring into AI-specific observability, Datadog appeals to teams already using it for traditional APM, letting them unify infrastructure and AI-specific monitoring within one familiar platform rather than managing entirely separate tooling.
Focused heavily on agent observability at scale, Galileo supports sub-200ms latency monitoring suited for real-time production use cases, with pricing models built around making continuous evaluation economically viable rather than prohibitively expensive at scale.
Coming from the team behind Pydantic and Pydantic AI, Logfire offers tight integration for Python-based AI applications, giving developers already working within that ecosystem a natural, low-friction path to adding observability.
Recognized for strong accuracy in no-code unstructured log analysis, Energent.ai analyzes spreadsheets, PDFs, and deep conversation traces without requiring manual coding, appealing to teams wanting powerful observability without extensive custom engineering investment.
As the industry moves toward standardizing AI telemetry, OpenTelemetry's GenAI-specific extensions provide a vendor-neutral foundation for instrumentation, letting teams avoid lock-in to a single observability provider while still capturing the detailed traces modern AI monitoring requires.
Tools alone don't solve the observability problem; strategy does. Teams practicing genuine AI native software development treat observability as a core design decision from day one, not something bolted on after launch.
Before instrumenting anything, teams need clear, specific quality criteria: what counts as a hallucination, what response time is acceptable, what task completion actually means.
Without this definition, observability data has nothing meaningful to measure against.
Capturing only the end result misses where problems actually originate: retrieval, reasoning, tool calls.
Comprehensive instrumentation across every layer lets teams pinpoint exactly where in a multi-step pipeline a failure occurred, rather than guessing based on a confusing final output alone.
Pre-launch testing alone misses the real-world inputs and edge cases that only appear once genuine users start interacting with the system.
Continuous, in-production evaluation catches degradation and drift that staged testing environments simply can't replicate accurately.
Traditional alerting triggers on errors and downtime. AI observability needs quality-aware alerting too, flagging when hallucination rates climb, retrieval relevance drops, or latency compounds beyond acceptable thresholds, catching silent quality degradation before users start complaining.
Production traces showing real failures should feed directly back into evaluation datasets, continuously improving test coverage based on actual, observed problems rather than hypothetical scenarios teams imagined during initial development and testing phases.
Teams need tooling that distinguishes between "the system is down" and "the system responded but gave a bad answer."
Conflating these two categories, as traditional monitoring often does, makes it nearly impossible to diagnose and fix the actual underlying problem quickly.
Not every failure carries equal weight. A minor latency issue in an internal tool matters less than a hallucination in a customer-facing financial recommendation.
Strategy should weight monitoring priority based on genuine business and reputational risk, not technical complexity alone.
AI systems drift, data changes, and user behavior evolves, meaning observability strategy needs regular revisiting rather than a single initial configuration.
Teams that treat this as continuous infrastructure, not a checkbox, catch problems that static, outdated monitoring setups inevitably miss over time.
AI observability has moved from a nice-to-have debugging tool to genuinely essential infrastructure, and the gap between teams that have it and teams flying blind keeps widening.
Traditional monitoring was never built to answer the question that actually matters for production AI: not whether the system responded, but whether that response was any good.
Whether you're monitoring a single LLM feature, a multi-step agent, or a RAG pipeline, the core principle stays the same: visibility into behavior and quality, not just uptime and latency, is what catches failures before users do.
As agent adoption keeps outpacing observability maturity across the industry, teams that invest in this now, with the right metrics, tools, and strategy, position themselves to catch problems early rather than discovering them through user complaints or, worse, real business harm.
AI observability is the practice of monitoring, evaluating, and debugging AI systems, LLMs, agents, and RAG pipelines, based on the quality and behavior of their outputs, not just infrastructure metrics like uptime and latency.
Traditional monitoring confirms a system responded successfully. AI observability evaluates whether that response was actually accurate, grounded, and genuinely useful, catching failures invisible to standard infrastructure dashboards.
Agents chain multiple reasoning steps and tool calls together, creating distinct failure modes, like inter-agent misalignment or inefficient reasoning loops, that single-call monitoring simply can't detect.
Grounding checks confirm that a generated response actually reflects the content of retrieved documents, rather than drifting into unsupported or fabricated claims despite having relevant source material available.
Non-deterministic behavior is the core challenge; the same prompt can produce different outputs across runs, making traditional, repeatable testing approaches fundamentally insufficient for catching quality issues.
Not necessarily. Many platforms like MLflow and Langfuse offer end-to-end observability covering all three, though some teams combine specialized tools for deeper coverage in specific areas.
Significantly. Enterprise losses from hallucinations alone were estimated at $67.4 billion in 2024, reflecting the real financial risk of deploying AI systems without adequate monitoring in place.
From day one. Teams practicing genuine AI native development treat observability as a core design decision during initial architecture, not something added after launch once problems have already surfaced.
Pre-launch testing uses controlled scenarios, while production observability captures real-world inputs, edge cases, and drift that only emerge once genuine users interact with the live system.
Track whether you're catching quality issues before users report them, whether token waste and latency are decreasing over time, and whether production failures are feeding back into improved evaluation datasets.
Bharat Sharma is the CTO of Techanic Infotech, bringing deep technical expertise in software architecture, mobile app development, and scalable system design. He leads the engineering team with a strong focus on innovation, performance, and security.