AI Development
AI-Ready Data Architecture: Building a Reliable Data Foundation for Enterprise AI Agents
October 16, 2026
October 16, 2026
Key Takeaways
An AI-ready data architecture provides the foundation enterprise AI agents need to access reliable information.
Data quality, governance, security, and accessibility are essential for dependable AI agent performance.
Both structured and unstructured enterprise data can support AI-driven applications.
APIs, data pipelines, vector databases, and integration layers help agents access relevant business information.
Enterprises should build their AI-ready data layer incrementally to support scalability and future AI adoption.
Enterprises are racing to deploy AI agents that answer questions, approve requests, and take action. But an agent is only as good as the data behind it. Feed it stale, scattered, or poorly labeled records, and it will confidently get things wrong.
That is why AI-ready data architecture has become a priority. It organizes, secures, and connects your data so agents can find the right information, understand what it means, and use it safely. Without it, pilots stall, costs climb, and trust fades.
This guide explains how to build the data layer for enterprise AI agents. You will learn the core layers, governance needs, implementation steps, tools, and costs, so your agents rest on a foundation you can truly trust.
AI-ready data architecture is the way you organize, govern, and connect your data so AI can use it safely. It goes beyond dashboards and reports. Here is what it means, and why it matters so much for enterprise AI agents.
AI-ready data goes beyond clean tables. It is data tied to specific use cases, labeled with clear meaning, governed by owners, and refreshed on the schedule AI needs.
That standard is stricter than analytics-ready data built for reports and dashboards.
Most organizations are not there yet. In a Gartner survey of data management leaders, 63% said they either lack the right data management practices for AI or are unsure they have them, a sign that confidence is lower than ambition.
The stakes are real. Gartner predicts that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data.
That figure covers projects lacking data readiness, not all AI work, but it shows how often weak data stalls good ideas.
Agents raise the stakes further. A chatbot answers questions, but an agent takes action: approving refunds, updating records, or routing orders.
That demands fresh data, clear permissions, and traceable sources, so a wrong record does not become a wrong decision.
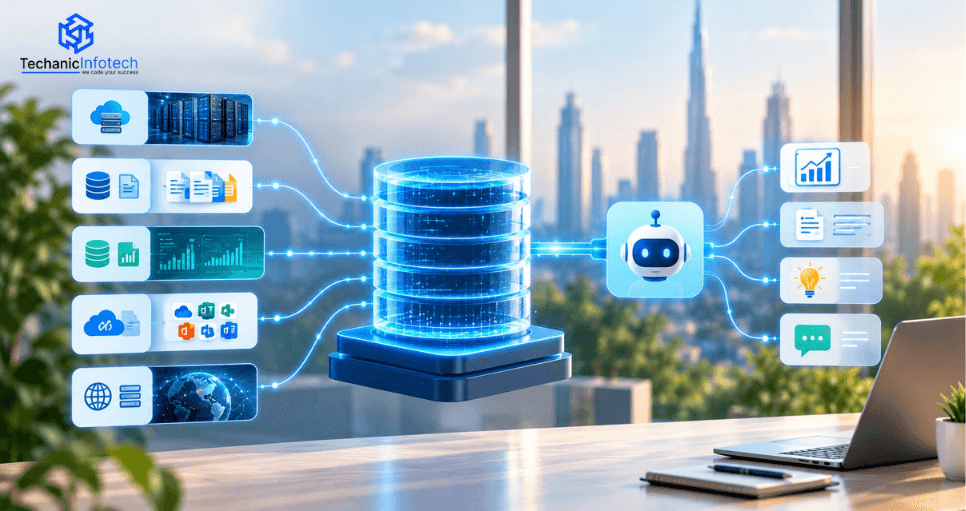
A strong data layer is built from parts that work together. Each one moves, stores, or explains data so agents can trust it.
Here are the core components of enterprise AI data architecture, from raw sources to governed, secure access.
Data starts in many places: apps, databases, SaaS tools, documents, and event streams. Pipelines move it using batch loads, change data capture, and streaming.
Reliable pipelines with built-in quality checks keep data fresh and catch problems before agents see them.
Store data where it can be queried and governed. Data lakes hold raw files, warehouses serve structured tables, and lakehouse platforms combine both.
Open table formats like Iceberg and Delta Lake reduce lock-in and let tools read the same data.
Agents and apps need fast, controlled access. A serving layer exposes data through APIs, caches, and event streams.
Good mobile app architecture depends on this layer, since the same governed APIs can feed customer apps, internal tools, and AI agents.
Agents often need to find meaning, not exact words. Embeddings turn documents, tickets, and records into vectors stored in a vector database, or in PostgreSQL with pgvector.
Hybrid search, combining keywords and vectors, usually returns the most relevant passages quickly.
Agents need to know what data means. A data catalog records owners, definitions, and lineage, while a semantic layer defines shared terms like "active customer" or "net revenue."
This context stops agents from guessing and keeps answers consistent across teams.
Every layer needs guardrails. Apply access controls so agents see only what their users may see, mask sensitive fields, and log every query. Monitor data quality, freshness, and drift, so teams quickly fix broken data before it reaches an agent.
Agents are demanding users. They query often, expect answers in seconds, and act on what they find. Meeting those demands means planning your AI data infrastructure around speed, freshness, scale, and control.
Agents may make dozens of data calls to finish one task. Slow queries add up, and users notice. Use indexes, caching, read replicas, and fast storage for hot data, and set latency targets for each agent workflow.
An agent working from last week's numbers makes last week's decisions. Stream changes from source systems with change data capture and event streams, so inventory, orders, and customer records stay current. Decide which data needs seconds, minutes, or daily freshness.
Agent traffic is unpredictable. Cloud computing for businesses lets you scale compute and storage up during busy periods and down when demand falls. Separate storage from compute, use autoscaling, and track cost per agent task, so growth doesn't become a surprise bill.
Agents amplify bad data and outages. Build in redundancy, backups, and failover, plus automated quality checks for missing, duplicate, or out-of-range values. When a pipeline breaks, agents should fall back safely or pause, not guess from stale data.
Agents act on behalf of people, so their data access must match their users' permissions. Use role- and attribute-based access controls, encryption, masking for sensitive fields, and full audit logs. Align with rules like GDPR and HIPAA, and keep data inside required regions.
Agents need more than raw tables. A context layer for AI combines retrieval, business definitions, lineage, and short-term and long-term memory, so agents find the right facts and understand them. Version and test this layer like any other production system.
Great data is useless if it can't flow to the right place. Pipelines connect sources, clean records, and feed models, search, and a knowledge graph for AI agents. These are the strategies that keep that flow fast, accurate, and manageable.
Begin with what the agent must do, then list the data it needs and where that data lives. Map owners, formats, update speed, and sensitivity for each source. This keeps pipelines focused on useful data instead of moving everything everywhere.
Match the pipeline style to the need. Batch ELT suits daily reports and model training, while change data capture and event streaming serve agents that need current records. Many enterprises combine both, using tools like Fivetran, Airbyte, Kafka, or Debezium.
Validate data as it moves, not after problems appear. Add checks for schema changes, missing values, duplicates, and odd ranges, and agree on data contracts between producers and consumers. Failed checks should pause the pipeline and alert a named owner.
Documents, emails, and tickets need extra steps. Parse them, split them into meaningful chunks, add metadata like source, date, and permissions, then create embeddings for retrieval. Re-index when files change, so agents never answer from outdated or deleted company content.
Link customers, products, orders, and suppliers as connected entities. Graph relationships help agents answer multi-step questions, such as which orders a supplier delay affects, which flat tables handle poorly. Start with one domain, and expand as the value becomes clear.
Legacy systems hold critical data. Budget for legacy system maintenance while you connect them through APIs, change data capture, or middleware. Feed that data into a context layer for AI, so agents get consistent meaning without rebuilding every old system.
Use an orchestrator such as Airflow or Dagster to schedule jobs, manage dependencies, and retry failures. Make steps idempotent, so reruns never create duplicates. Track lineage and freshness on one dashboard, so teams see what broke and who owns it.
Secure pipelines like production systems. Encrypt data in transit, mask personal fields before indexing, and carry access permissions with each record, so agents respect user rights. Watch compute and storage costs by pipeline, and retire jobs that nobody uses anymore.
AI agents touch sensitive data, so security cannot be an add-on. Your vector database architecture, pipelines, and agents all need guardrails. Here is how to build security, governance, and compliance into AI-ready data from the start, not after an incident.
You cannot protect what you cannot see. Scan sources to find personal, financial, health, and confidential data, then tag it by sensitivity. Keep an inventory of what feeds each agent, so governance decisions start from facts, not guesses or assumptions.
An agent should never see more than the person using it. Enforce role- and attribute-based access at query time, pass user identity through to data stores, and apply row- and column-level rules, so agents cannot leak records users cannot open.
Encrypt data in transit and at rest, and manage keys. Mask or tokenize sensitive fields before they reach embeddings, logs, or prompts. Once personal data is embedded in a vector index, removing it later becomes harder, so protect it early.
Record where every answer came from. Track lineage from source to index to response, and log each query, retrieved document, and agent action with user and timestamp. When someone asks why an agent did something, you can answer with evidence.
Privacy laws apply to AI data too. Rules like GDPR, CCPA, and HIPAA call for lawful use, consent, data minimization, and honoring access and deletion requests. Build processes that find and remove a person's data across sources, indexes, and caches.
Governance should live in your context layer for AI, not in each agent. Store approved definitions, data owners, quality scores, and usage policies there, so every agent follows the same rules and a policy change takes effect everywhere at once.
AI adds new risks. Protect against prompt injection, poisoned documents, and data leakage through answers, and test agents with adversarial prompts. Frameworks like the NIST AI Risk Management Framework, ISO 42001, and the EU AI Act help structure your controls.
Governance needs owners. Name data stewards, set clear policies for approved sources, and review them regularly. Monitor quality, access patterns, and agent behavior continuously, and require human approval for high-risk actions, so accountability never gets lost between teams or systems.
Enterprise AI agents are only as reliable as the data behind them. An AI-ready data architecture gives agents clean, governed, and permissioned information to work with. Here are eight steps that help your team build one without starting over completely.
Every enterprise AI data architecture starts with an honest inventory. List your databases, SaaS tools, file stores, and spreadsheets. Note who owns each source and how often it changes. You can't connect what you haven't mapped. Gaps show up fast.
Agents don't live in a vacuum. They sit inside the apps your teams already use. Strong enterprise web application development connects your portals, CRMs, and internal tools to a shared data layer, so agents see the same facts employees do.
Agents query data constantly, often in bursts. Your AI data infrastructure needs fast storage, reliable pipelines, and room to grow. Cloud data warehouses and lakehouses work well here. Pick tools your team can actually maintain, not whatever sounds most impressive.
Raw data confuses agents. A context layer for AI adds meaning on top of it. Define business terms, relationships, and metrics once. Then every agent reads revenue, customer, or churn the same way, instead of guessing from messy column names.
Bad data produces confident wrong answers. Remove duplicates, fix formats, and fill gaps in your most important sources first. Set quality checks that run automatically. Clean data won't fix everything, but dirty data will break agent workflows sooner or later.
Agents often need answers from documents, emails, and policies. Index that content with embeddings so agents can search by meaning, not just keywords. Pair vector search with your regular database. Use each one for what it does best. Both matter.
Agents should only see what the person asking is allowed to see. Apply role-based access, encryption, and audit logs at the data layer, not inside prompts. Never trust the model to decide who gets access to what. Be strict.
You don't have to build all of this alone. A software development company can design the pipelines, governance, and integrations around your systems. Look for enterprise experience, strong security practices, and a team willing to start with one use case.
An AI-ready data architecture gives enterprise AI agents the reliable, accessible, and governed data foundation they need to perform effectively.
A well-designed data layer connects structured and unstructured information across business systems while maintaining quality, security, scalability, and governance.
Enterprises should focus on strong data pipelines, integration frameworks, metadata management, storage systems, APIs, and access controls when preparing their infrastructure for AI agents.
Data architecture should also support real-time processing and contextual retrieval so AI agents can access relevant information when needed.
As enterprise AI adoption grows, organizations that invest in flexible and scalable data foundations can deploy intelligent agents more efficiently.
Building this architecture incrementally allows businesses to improve existing infrastructure while preparing their data environment for increasingly autonomous, intelligent, and data-driven enterprise applications.
An AI-ready data architecture is a data infrastructure designed to provide AI systems and enterprise agents with reliable, accessible, secure, and well-governed data for analysis and decision-making.
Enterprise AI agents depend on accurate and relevant information to complete tasks. A strong data architecture helps agents access trusted data while maintaining security, governance, and performance.
Key components include data lakes or warehouses, integration pipelines, APIs, databases, metadata management, vector databases, data governance tools, security controls, and monitoring systems.
Poor-quality, outdated, duplicated, or incomplete data can lead to unreliable AI outputs. Strong validation, cleansing, monitoring, and governance processes help provide agents with more trustworthy information.
Yes. Enterprise AI agents often need both structured data, such as databases and spreadsheets, and unstructured information, including documents, emails, images, and knowledge bases.
APIs allow AI agents to securely access information and interact with enterprise applications. They can connect agents with CRM, ERP, databases, customer platforms, and other business systems.
A vector database can be useful for applications requiring semantic search and retrieval-augmented generation. It helps AI systems find relevant information based on meaning rather than only exact keywords.
Organizations can use encryption, identity management, role-based access controls, authentication, data masking, monitoring, audit logs, and governance policies to protect sensitive enterprise information.
In many cases, existing infrastructure can serve as the foundation. However, organizations may need improvements in data quality, integration, accessibility, governance, metadata, and real-time processing capabilities.
Businesses should begin by assessing existing data sources and identifying AI use cases. They can then improve data quality, establish governance, connect systems, build pipelines, and gradually introduce advanced AI capabilities.
Bharat Sharma is the CTO of Techanic Infotech, bringing deep technical expertise in software architecture, mobile app development, and scalable system design. He leads the engineering team with a strong focus on innovation, performance, and security.